Review Data Structured for AI Shopping Agent Consumption
Agents need structured review data to evaluate products before shoppers see results.
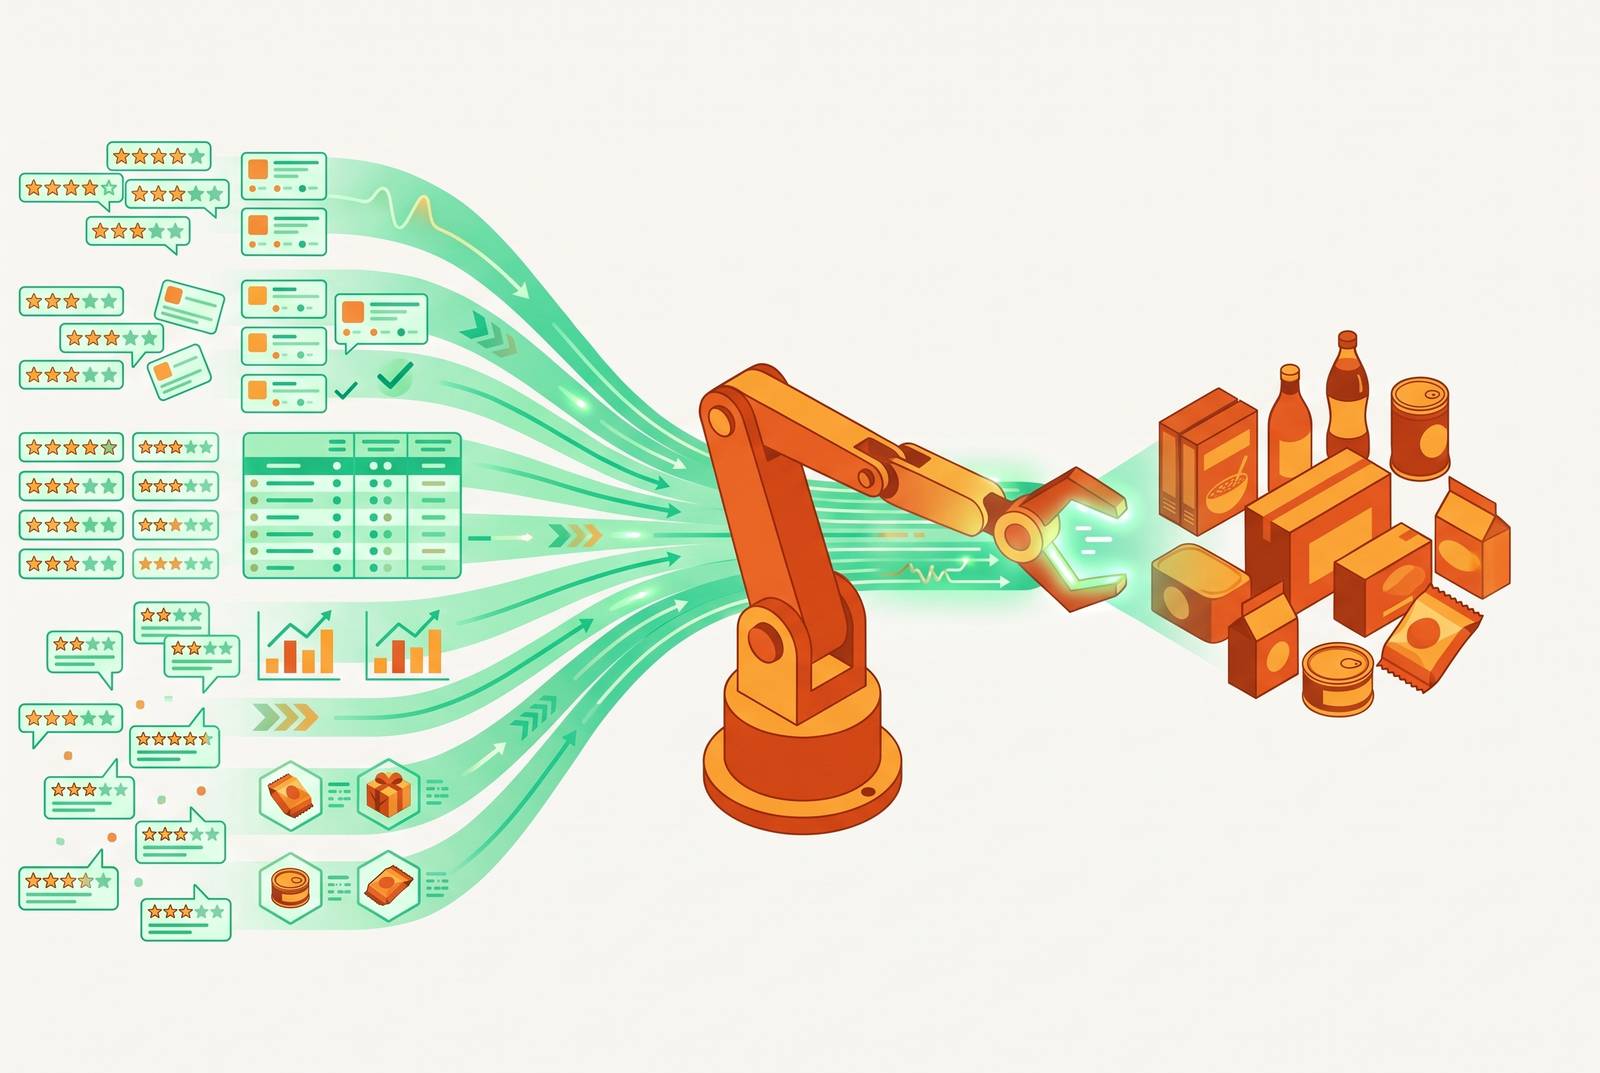
Review data structured for AI shopping agent consumption is part of a brand’s AI-readiness infrastructure. As agents compare products before shoppers see them, reviews must provide evidence that machines can attribute, interpret, and match to a buyer’s needs. The competitive advantage lies in organizing that evidence around verified reviewers, specific attributes, and the exact product variant under consideration.
How AI shopping agents actually evaluate products before a human sees the results
BigCommerce’s merchant guide sets out a four-stage shopping journey that starts when a shopper says what they need. The agent retrieves candidates from feeds, Shopping Graph, or a crawl, then evaluates them and produces a shortlist. The shopper completes the purchase through a merchant-site redirect, in-assistant checkout, or Perplexity’s Buy with Pro. Evaluation precedes the shopper’s view of the results. At that point, the agent compares product attributes, live price and availability, shipping terms, and third-party reviews.
This sequence changes where a product can lose consideration. A stale feed or a price mismatch between the feed and the site can remove a candidate during evaluation, before a purchase reaches checkout. The customer never sees the rejected option. Page design cannot repair that failure because the comparison operates on product data. Complete, accurate, machine-readable information is the input a brand can control at this stage.
Alavi & Nozari’s 2026 paper shows how a consumer looking for wireless headphones hands this work to an agent. Instead of scrolling through results and comparing specifications, the consumer hands the task to a buyer agent operating between consumer and seller. The interface becomes a statement of need. The agent’s subsequent work includes finding and comparing products, which places the burden of explanation on the data it can retrieve. Reviews enter that comparison before a human has an opportunity to interpret them.
Why reviews specifically are a gating signal, not just social proof
A description states what the seller claims, while customer-generated and third-party reviews offer a basis for assessing those claims from outside the seller’s account. That distinction gives reviews their role in evaluation. The merchant guide identifies third-party reviews as a separate comparison input for ChatGPT, Google AI Mode, and Perplexity, together with price and availability.
An agent acting for a buyer needs enough context to determine what a review supports and whether it applies to the product being considered. An unattributed star average answers neither question reliably. A smaller review set can be more useful when it identifies who reviewed, what was verified, and which attributes the reviewer addressed. Volume becomes valuable when it adds interpretable evidence.
Ventirozos & Shardlow’s paper on agentic e-commerce identifies the scarce resource as “trustworthy, decision-relevant information”. Their argument distinguishes that resource from information that is “free but unverified,” explicitly including unaudited star ratings in the latter category. Properly structured reviews let an agent check a claim against more than the seller’s own copy, though structure alone does not prove the claim is true. This is why reviews can help gate entry to a shortlist rather than simply reassure a shopper after discovery.
What structured review data looks like versus what most brands actually publish
Most brands publish reviews for people reading a product page. The familiar format combines an aggregate star rating, a freeform paragraph, a reviewer display name, and a date, often spread across pagination. Much of the interpretation remains implicit. A person may infer that a comment concerns fit or compatibility, but an agent needs those relationships made clear enough to evaluate without guessing. Human-readable content is not the same as structured evidence.
Useful review data identifies the reviewer, purchase verification status, the product variant reviewed, the attribute discussed, and a rating tied to that attribute. Each element resolves a different ambiguity for the agent. Verification concerns the reviewer’s relationship to the purchase, while variant attribution establishes which configuration the evidence describes. An attribute-specific rating then shows whether the review supports the buyer’s particular requirement.
Schema provides a basic way to express some of these relationships. Relevant Product markup includes name and at least one of review, aggregateRating, or offers, while Review fields such as author, datePublished, reviewRating, and reviewBody make review content parseable and attributed. These fields are a starting point. A review of a size-small red jacket attached only to a parent product ID does not establish its relevance to a size-large black variant.
What Google added to Merchant Center in May 2026 shows where the platform’s requirements are heading. The six optional feed attributes are question_and_answer, related_product, variant_option, item_group_title, popularity_rank, and document_link. They provide more structured context for AI shopping. These are feed attributes, and variant_option is not a Schema.org property. Their introduction reinforces the distinction between publishing a readable page and supplying explicit product relationships through the channels an agent uses.
How each major AI shopping surface reads review signals differently
ChatGPT, Google AI Mode, and Perplexity do not retrieve review evidence through identical pipelines. Their shared need for machine-readable product data does not mean one publication channel reaches all three equally. Distribution is part of the structural problem. A review corpus can be well organized on the merchant’s site yet poorly represented in a feed or absent from the third-party sources another surface consults.
ChatGPT draws from merchant feeds and web crawl, evaluating feed data, price, availability, and reviews. Review information can therefore enter through feeds and crawled on-site schema. As of September 2026, ChatGPT defaults to a merchant redirect and has been discovery-first since March 2026.
Google AI Mode makes Merchant Center feeds and Google’s structured data index relevant to review accessibility. Its UCP path offers in-assistant checkout in Early Access as of September 2026. Perplexity, by contrast, makes third-party review presence important through its cited-source evaluation and offers Buy with Pro for in-assistant purchasing. Checkout is not uniform across these surfaces. The connection between review evaluation and conversion is more direct where the shopper can complete the purchase inside the assistant.
The practical requirement is coverage across these reading modes. On-site schema, feed-level review data, and third-party review presence serve different retrieval paths. None substitutes fully for the others. The merchant guide states that “all three run on complete, accurate product data — and organic placement can't be bought”.
The verification problem: why unaudited ratings are becoming a liability
An agent may be able to extract an average precisely while still lacking a basis for judging who contributed to it or whether those contributors purchased the product. Verification supplies a separate layer of evidence. Without structured purchase attribution, the review corpus does not give the agent a machine-readable distinction between a verified buyer’s account, an editorial comment, and an unverified submission.
Ventirozos & Shardlow propose a market architecture in which “reviewer trust scored reputationally” would help determine the value of information. Their proposal would make reviewer track record relevant, rather than treating all submissions as equivalent contributions to volume. This is a research direction. It explains why a corpus built only around unaudited averages is poorly prepared for more demanding evaluation, without establishing that today’s major shopping agents systematically discount every unverified rating.
Alavi & Nozari identify a related trust problem in the relationship between buyer and seller agents. Their preference-leakage research shows that seller-side agents can infer consumer willingness to pay from buyer-agent dialogue. That finding establishes an information asymmetry between buyer and seller agents that strengthens the case for buyer-side caution about seller-controlled claims and for evidence obtained at arm’s length.
For brands, the exposure is therefore structural rather than a demonstrated universal loss of visibility. Verified-purchase attribution gives agents a basis for distinguishing kinds of testimony, even though it does not prove every statement in a review. As agents put more weight on verification, they may give less weight to or ignore a large but unaudited corpus just where a brand expects it to reassure the buyer.
Attribute-level and variant-level review structure as the practical implementation gap
The implementation priority is to connect review evidence to the question an agent is answering. Reviews should identify the attributes they address, including fit, durability, flavor intensity, compatibility, and ease of assembly. A durability query needs durability evidence. An overall average blends those concerns together, leaving the agent to infer whether a favorable rating reflects the feature the buyer actually values. Attribute tagging makes the relevant portion of the review corpus retrievable as evidence for that requirement.
Variant attribution resolves a different problem within the same comparison. Review schema should connect the review to the specific SKU or variant reviewed, distinguishing it from the parent product ID. The distinction limits inappropriate generalization across product configurations. A review about a size-small red item is not automatically equivalent evidence for a size-large black item, even when both belong to the same product family. The agent needs to know the scope of the reviewer’s experience before applying it to a candidate.
Feed-to-site consistency then keeps those relationships coherent across retrieval paths. The merchant guide identifies “data that doesn't match between your feed and your site” as a root cause of visibility failure. Review data can create the same kind of mismatch. If a feed describes one variant while on-site review markup refers to another configuration, the evidence no longer aligns with the candidate under evaluation. Likewise, an aggregate rating in a feed and a different review corpus in on-site schema reduce confidence in what the rating represents.
FAQ-structured product content provides a complementary layer for questions that recur in support tickets, live chat transcripts, and reviews. Headings that state the question, followed by factual answers, give agents content they can parse that addresses what buyers want to know. This serves a different purpose from review attribution. It makes the questions and answers accessible, but it does not establish the purchase status or product experience of an individual reviewer. Google deprecated FAQ rich results as of May 2026, so the value of this content should not be confused with expandable Q&A rich results from FAQPage markup in Google Search.
Review structure as a brand's competitive moat in AI-mediated discovery
A brand that has collected attribute-level and variant-level reviews for two years has more than a larger body of text. It has a history of specific product experiences. A competitor that starts later cannot quickly build the same attributed record, even if it can copy a page layout or add similar schema fields. The durable asset is the corpus and its relationships.
That edge matters as more products are found before a shopper reaches a merchant page. The merchant guide says that vast numbers of people use ChatGPT every week, so being seen in AI results matters well beyond a niche channel. When evidence is incomplete, an outside model must assemble a product assessment from the signals it can find, with less of the brand’s own customer experience available in a usable form.
As checkout develops, this preparation becomes more valuable, though some paths to purchase are still further along than others. The guide recommends joining waitlists for agentic checkout programs so in-assistant buying can be enabled as those programs develop. Review readiness precedes that commercial handoff. Even when a new checkout path makes buying easy, a product still needs enough evidence to make it through the comparison.
The strategic decision is therefore about what future review collection preserves. Ratings gathered without reviewer attribution, attribute context, or variant identity leave gaps that a later technical cleanup cannot simply fill. Brands building those relationships into their review data retain more of what customers actually establish about their products. When an agent compares candidates, that record gives it evidence to evaluate.